The R&D Resurrection Trade: AI Agents Are Reopening Abandoned Science
How AI agent swarms could uncover value in abandoned research, shelved drug programs and dormant IP, while shifting science’s bottleneck from thinking to proving.
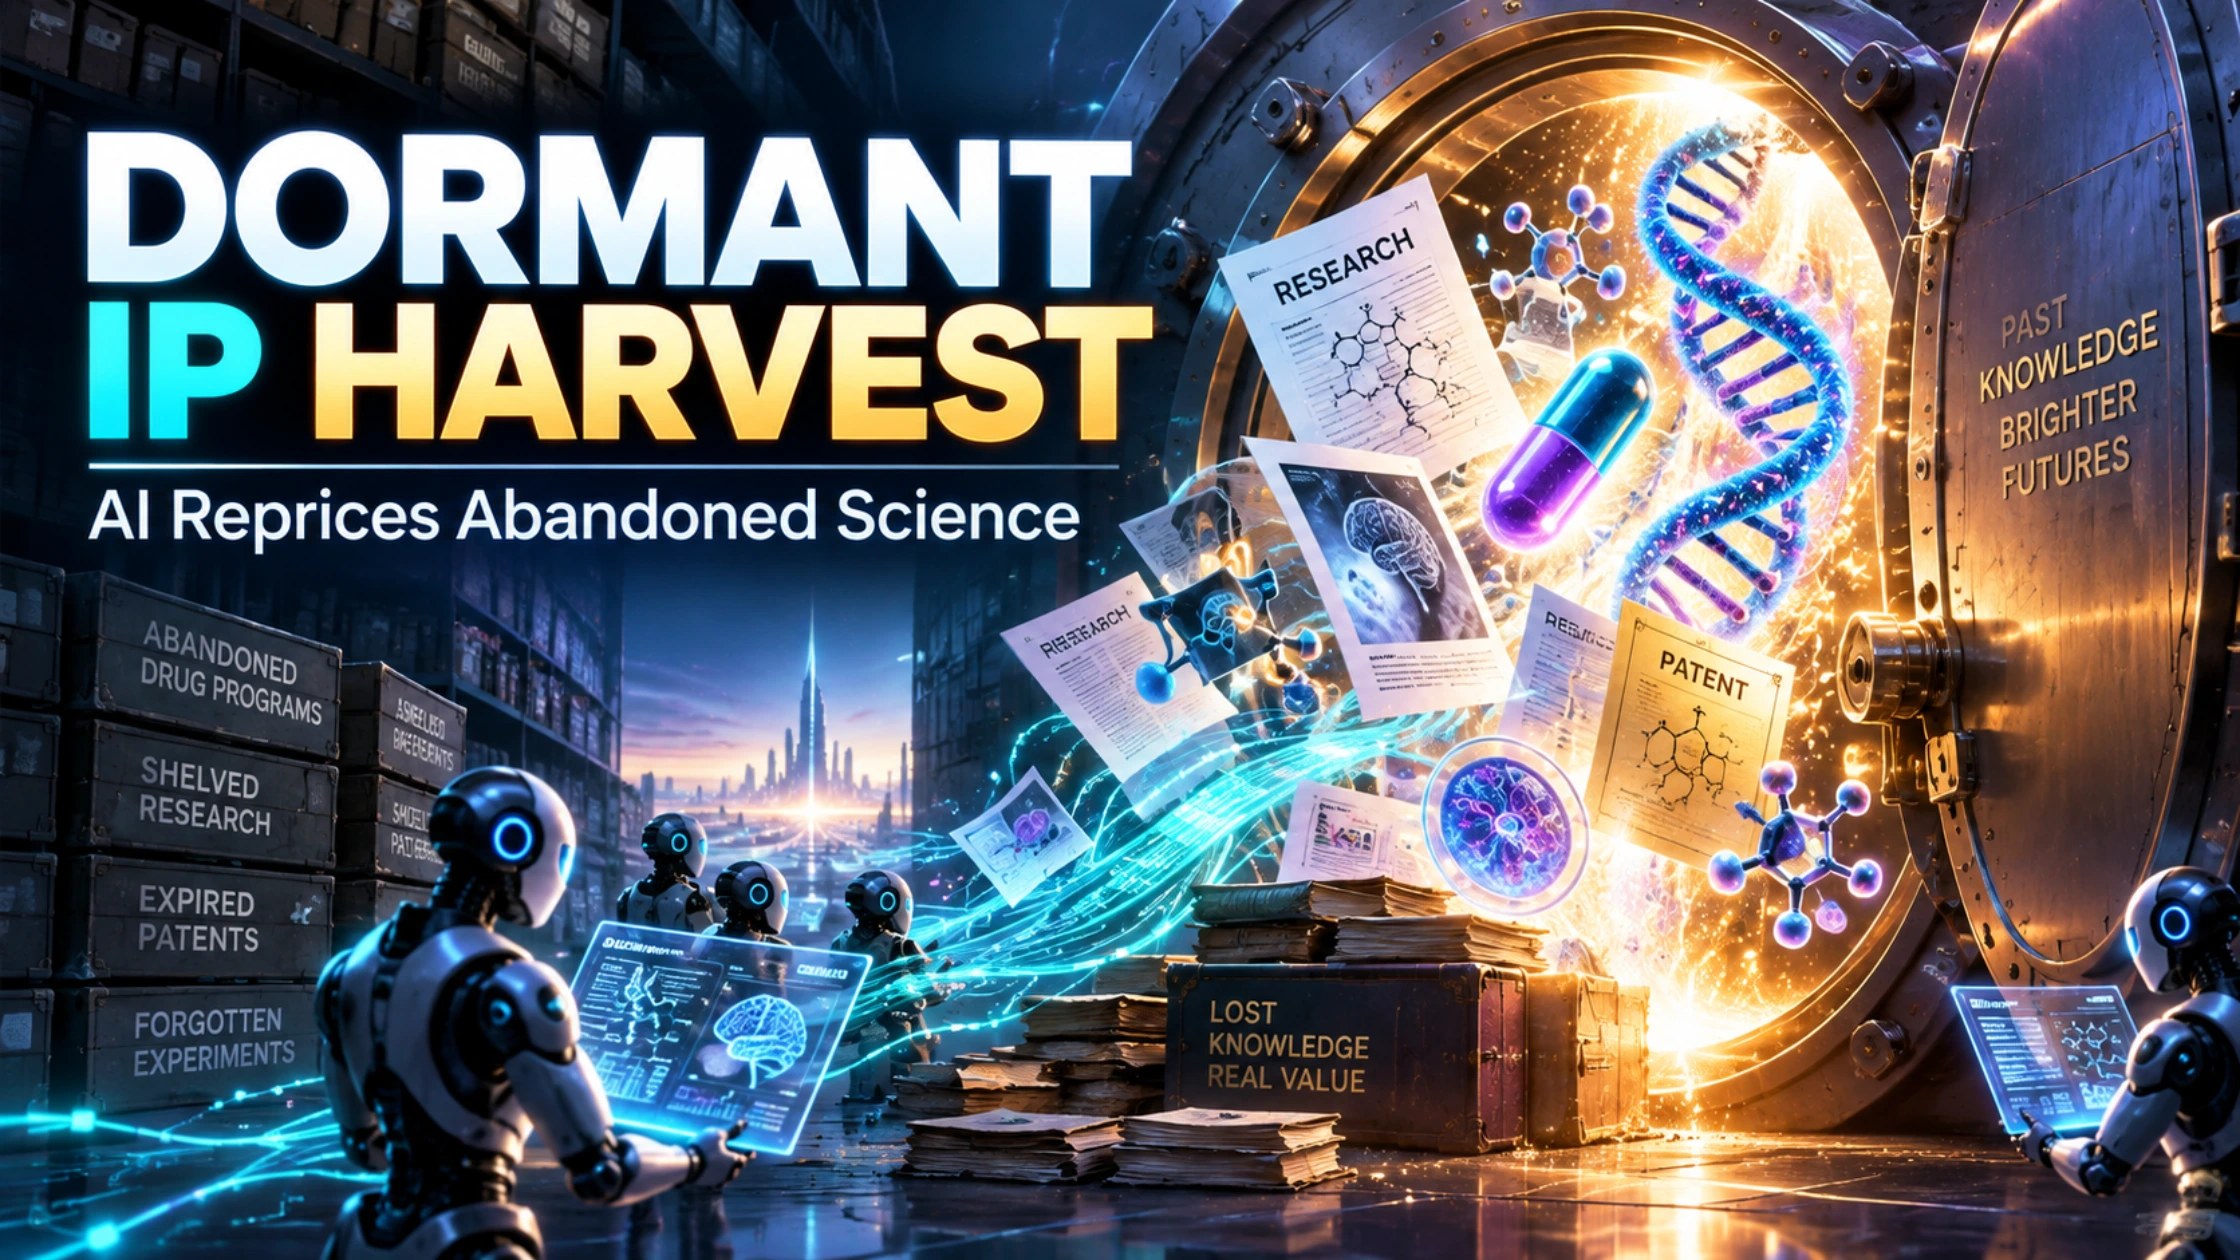
The Dormant IP Harvest: How AI Agent Swarms Could Reprice Abandoned Science
AI may not need to invent every breakthrough from scratch. A more immediate opportunity is buried across failed drug programs, static research papers, abandoned experiments, old patents and disconnected datasets. Agent swarms are making that knowledge searchable, combinable and executable at a scale humans have never had.
The Signal
- Scientific progress does not fail only because humanity lacks ideas. It also fails because knowledge is fragmented across papers, companies, databases, patents, failed experiments and research teams that never find one another.
- Stanford's Paper2Agent now converts scientific papers into interactive agents that can reproduce methods, interrogate datasets and collaborate with agents built from other papers. In one demonstration, two unrelated paper agents generated a previously unreported candidate mechanism connected to ADHD risk.
- Stanford's Virtual Biotech used more than 37,000 agents to analyse 55,984 clinical trials and coordinate work across drug-development functions.
- A separate 2026 analysis identified 5,523 drug-development programs that appear to have been deprioritized after reaching human clinical trials. The authors argue that at least a subset may retain scientific or commercial option value.
- OpenAI says roughly 10,000 concurrent agents helped produce its proposed solution to the Navier-Stokes Millennium Prize problem. The announcement remains the subject of broader verification and attribution debate, but the scale of coordinated machine reasoning is itself economically significant.
- The important economic consequence may not be that AI replaces scientists. It may be that AI dramatically lowers the Coordination Tax required to search, compare and recombine existing human knowledge.
- If hypothesis generation becomes abundant, scarcity shifts downstream toward experiments, high-quality data, biological samples, wet labs, clinical access, IP rights, reproducibility and scientific provenance.
- DN calls the resulting opportunity the Dormant IP Harvest.
Science has a storage problem disguised as an intelligence problem.
Humanity has spent centuries producing:
- papers,
- patents,
- clinical trials,
- negative results,
- abandoned molecules,
- failed prototypes,
- experimental datasets,
- source code,
- lab notebooks,
- and partial solutions.
Most of this knowledge does not disappear.
It becomes difficult to find.
Difficult to understand.
Difficult to combine.
Difficult to reproduce.
Or commercially inconvenient to revisit.
The result is an enormous archive of intellectual work that sits somewhere between useless and valuable.
The difference often depends on whether the right person discovers the right fragment at the right moment.
AI agents change that search process.
The R&D Graveyard Is Larger Than It Looks
Consider drug development.
A candidate can be discontinued because it is unsafe.
It can fail because it does not work.
Those failures matter.
AI does not repeal biology.
But programs are also abandoned because:
- a company changes strategy,
- capital disappears,
- a merger removes a program,
- a competing therapy changes commercial economics,
- a biomarker is not yet understood,
- a trial is poorly designed,
- a different indication looks more promising,
- patent life becomes unattractive,
- or management simply chooses another asset.
A 2026 Drug Discovery Today study attempted to quantify this hidden inventory.
Researchers identified 5,523 drug-development programs that appeared to have been deprioritized after entering human trials.
The authors are careful.
Many may have been discontinued for sound scientific reasons not visible in public information.
But the study argues that a subset could retain scientific or commercial option value under different development strategies.
That is an extraordinary inventory.
These are not merely theoretical molecules drawn on a computer.
They are programs that had already crossed at least part of the expensive bridge into human development.
AI could transform abandoned R&D from a collection of forgotten projects into a searchable options portfolio. The value is not that every failed project becomes viable. The value is that machines can cheaply identify which tiny fraction deserves another look.
The Hidden Cost of Science Is Coordination
Scientific research usually gets described as a problem of intelligence.
Find smarter researchers.
Generate better hypotheses.
Design better experiments.
But there is another cost.
DN calls it the:
Coordination Tax.
It is the economic and temporal cost of:
- finding relevant work,
- reading it,
- understanding unfamiliar methods,
- finding compatible datasets,
- contacting another research group,
- recreating their software,
- translating file formats,
- checking assumptions,
- reproducing analyses,
- and realizing that two apparently unrelated projects can be combined.
Human expertise is enormously powerful.
Human attention is not infinitely parallel.
There are simply too many papers.
Too many datasets.
Too many abandoned programs.
Too many combinations.
Paper2Agent Changes What a Paper Is
For hundreds of years, the academic paper has essentially been passive infrastructure.
A scientist publishes.
Another scientist finds the paper.
Reads it.
Interprets the methods.
Finds the data.
Attempts to reproduce it.
Then perhaps applies the technique somewhere else.
Stanford's Paper2Agent architecture changes that model.
It converts a manuscript, including methods and data resources, into an interactive agent.
The agent can explain the work.
It can apply the methods.
And crucially, it can interact with another paper agent.
Stanford demonstrated this by connecting agents built from two separate genomics papers.
The resulting system produced a candidate mechanistic hypothesis linking a genetic variant to ADHD risk.
That hypothesis still requires experimental validation.
That qualification is important.
But economically the mechanism matters even before the hypothesis is proven.
The scientific paper may evolve from a record of knowledge into an executable knowledge object. Once papers can query, calculate and collaborate, the value of an archive changes because its contents can participate actively in discovery.
Static Knowledge Is Becoming Agentic Capital
This suggests a broader framework.
A research paper today is valuable when someone reads it.
A dataset is valuable when someone knows how to query it.
A failed drug program is valuable when someone remembers it exists.
A patent portfolio is valuable when someone recognizes a relevant claim.
Agentic systems reduce that dependency on human recollection.
Knowledge can become continuously interrogated.
Its value therefore changes from:
What does this document contain?
toward:
What can machines do with what this document contains?
DN calls the difference:
The Dormant Knowledge Premium.
It is the additional economic option value created when previously passive information becomes machine-searchable, reproducible and recombinable.
37,000 Agents Point Toward a Different Research Organization
Stanford's Virtual Biotech provides an even more dramatic example.
The system is organized less like a chatbot and more like a company.
A virtual chief scientific officer coordinates specialized agents working across functions such as:
- target discovery,
- genomics,
- safety,
- therapeutic modality,
- and clinical development.
More than 37,000 agents were deployed to analyse tens of thousands of clinical trials.
One agent could focus on one trial.
Thousands of individual outputs could then be standardized and compared.
That is not simply faster reading.
It represents a different organizational form.
A human company cannot hire 37,000 analysts for one research question and then dismiss them when the analysis finishes.
Software can approximate this kind of temporary intellectual labour.
The Manhattan Project Comparison Is Tempting, but Incomplete
It is easy to look at these systems and conclude that science is about to become trivial.
That would be a mistake.
Current benchmarks still show large gaps.
Stanford's 2026 AI Index reports that the best tested multi-agent configuration on PaperArena achieved 38.8% accuracy.
The PhD expert baseline was 83.5%.
On BixBench, frontier systems reached only around 17% on realistic bioinformatics tasks.
Other scientific replication benchmarks remain difficult too.
AI can simultaneously:
- produce remarkable discoveries,
- scale research labour dramatically,
- and remain unreliable at many ordinary scientific workflows.
Those statements are not contradictory.
Frontier capabilities are highly uneven.
OpenAI's Mathematics Experiment Shows the Scaling Extreme
OpenAI says its September 2026 Navier-Stokes project used on the order of 10,000 concurrent agents.
The agents exchanged millions of messages and consumed enormous amounts of inference.
OpenAI says the group reached its proposed resolution after roughly 88 hours, followed by formalization and verification in Lean.
The mathematical community is still debating broader verification, attribution and research credit.
That debate should not be waved away.
But there is already an economic lesson.
Test-time compute is becoming research labour.
A company can increasingly decide to spend more:
- tokens,
- agents,
- tool calls,
- parallel searches,
- simulations,
- and verification passes
against a single intellectual problem.
Scientific labour is acquiring a new scaling variable: Research Compute Intensity. Some problems that once depended almost entirely on scarce human attention can increasingly absorb capital directly through agent inference, parallel search and automated verification.
This Could Change the Economics of R&D
Traditional R&D contains a hard organizational constraint.
More money does not instantly create more elite researchers.
A company cannot hire 10,000 world-class specialists tomorrow.
Even if it could, coordination costs would explode.
Agent systems partly change this relationship.
Capital can buy:
- more model inference,
- more parallel hypotheses,
- more literature searches,
- more code execution,
- more simulated debates,
- and more automated replication attempts.
This does not make physical experiments disappear.
Instead it moves the bottleneck.
The Bottleneck Moves From Thinking to Proving
If the cost of generating plausible hypotheses falls by 90%, science does not become 90% cheaper.
Something else becomes scarce.
Researchers still need:
- cell lines,
- animals where scientifically justified,
- chemistry,
- microscopes,
- sequencers,
- robotics,
- manufacturing,
- clinical participants,
- regulatory approval,
- and time.
This produces a paradox.
AI can make discovery faster while making experimentation feel slower.
Not because labs deteriorate.
Because the queue of ideas trying to enter the lab becomes much larger.
DN calls this:
Hypothesis Inflation.
When machine-generated hypotheses scale faster than experimental throughput, the scarce asset in science becomes Validation Capital: the laboratories, samples, clinical networks, instrumentation, regulatory pathways and high-quality datasets capable of proving which machine-generated ideas survive reality.
The Hypothesis-to-Lab Ratio
DN proposes a simple metric:
Hypothesis-to-Lab Ratio.
Suppose an organization historically generated 100 serious testable ideas per year and could experimentally evaluate 80.
Its ratio was 1.25.
Now suppose agent systems generate 5,000 credible candidates while physical capacity can validate only 120.
The ratio becomes more than 40.
The organization's problem is no longer idea scarcity.
It is experiment allocation.
The key AI system may therefore not be the model generating more hypotheses.
It may be the system that decides which 120 deserve scarce laboratory capacity.
Prediction Becomes Less Valuable Than Prioritization
This creates an underappreciated change in AI product value.
Today, many scientific AI companies sell:
prediction.
Predict this molecule.
Predict this target.
Predict this property.
Predict this structure.
As prediction becomes abundant, the more valuable question becomes:
Which prediction should consume real-world capital?
That requires much more than model confidence.
It requires:
- causal evidence,
- reproducibility,
- safety evidence,
- experimental feasibility,
- rights clarity,
- commercial relevance,
- and consideration of what evidence would actually falsify the thesis.
Failed Drugs Could Become Machine-Readable Options
The 5,523 shelved clinical-stage programs illustrate the possibility.
Do not read that number as 5,523 hidden winners.
That would be absurd.
Most failed or discontinued programs may remain unattractive.
But the cost of evaluating the portfolio is changing.
Historically, a company considering one abandoned molecule might need to assign scientists to reconstruct:
- what was tried,
- why it stopped,
- what safety data exist,
- what patents remain,
- which biomarkers were used,
- whether disease classification has changed,
- whether new combination therapies exist,
- and whether new delivery technologies alter the equation.
Now imagine agents performing the first-pass reconstruction across thousands of assets.
The economic value does not come from automatically restarting them.
It comes from reducing 5,523 possibilities into perhaps 50 worth human diligence.
Then perhaps five worth experimental validation.
Then perhaps one worth restarting.
DN Scientific Option Value
DN calls the residual value of a shelved research asset:
Scientific Option Value.
The option becomes more valuable when:
- substantial prior validation already exists,
- safety information is available,
- the underlying data are accessible,
- rights are clear,
- new scientific evidence changes the original thesis,
- new technology solves an earlier constraint,
- and experimental re-testing is affordable.
Scientific Option Value falls when:
- the original program failed for fundamental biological reasons,
- data cannot be reconstructed,
- ownership is disputed,
- patent protection is weak,
- the necessary experiments are prohibitively expensive,
- or the market opportunity has disappeared.
Yesterday's Failure Can Meet Tomorrow's Technology
A failed research program is not always being judged against the same technological environment forever.
A program abandoned in 2012 could encounter:
- better biomarkers,
- cheaper genomic sequencing,
- improved protein modelling,
- new delivery platforms,
- more precise patient segmentation,
- better diagnostics,
- new manufacturing processes,
- or an entirely different disease classification.
The underlying molecule may not have changed.
The surrounding feasibility landscape has.
This is why old research can acquire new option value.
The FDA Is Already Looking at Repurposing
The timing matters.
In 2026, the US Food and Drug Administration opened a formal effort focused on drug repurposing for unmet medical needs.
The FDA has highlighted an obvious advantage.
An existing approved medicine can come with information about:
- safety,
- manufacturing,
- dosing,
- and real-world clinical experience.
That does not guarantee efficacy in a new indication.
But it can reduce certain uncertainties compared with starting from zero.
The important economic implication is that the regulatory system itself is beginning to pay more attention to systematic reuse of existing scientific assets.
AI Creates a Machine-Readable IP Discount
Not all dormant research will benefit equally.
Suppose Company A has 20 years of experiments stored in:
- clean databases,
- structured metadata,
- linked assay results,
- versioned code,
- clear ownership records,
- standardized clinical documents,
- and machine-accessible APIs.
Company B has the same scientific history spread across:
- PDFs,
- email attachments,
- obsolete file formats,
- retired laboratory systems,
- unlabelled spreadsheets,
- and notebooks nobody can locate.
Historically, the scientific content could be equally valuable.
In an agentic research environment, it is not equally usable.
DN calls the valuation penalty:
The Machine-Readable IP Discount.
Data hygiene is becoming part of intellectual-property value. Two companies can own equally strong historical research, but the company whose evidence can be reliably consumed, traced and reproduced by machines may possess the more valuable portfolio.
Negative Results Could Become More Valuable
Science has historically struggled with negative-result publication.
A failed experiment is difficult to celebrate.
It can be commercially sensitive.
It may never become a paper.
That creates duplication.
Researchers can spend time discovering paths others already learned do not work.
Agents change the economics of negative information.
A machine capable of screening millions of combinations benefits enormously from knowing:
where not to look.
A database of failed reactions, rejected targets, adverse signals or non-replicating experiments can prune the search tree.
Negative data therefore becomes training infrastructure.
The Failed Experiment Becomes a Map
Imagine two search systems.
One knows only successful scientific papers.
The other knows:
- the successful papers,
- failed experiments,
- abandoned clinical programs,
- rejected compounds,
- and explanations for why they failed.
The second system possesses a map of explored dead ends.
That can make its remaining search space much more valuable.
In an agentic R&D economy, failure data can appreciate. Information that was commercially embarrassing or publication-ineligible in a human research system can become valuable machine context because it prevents millions of repeated mistakes.
The Real Moat Could Be Proprietary Research Memory
This creates a different way to think about competitive advantage.
Companies frequently focus on access to the best frontier model.
Model access may become widely distributed.
The harder asset to reproduce may be:
institutional research memory.
A pharmaceutical company can possess decades of:
- failed trials,
- compound libraries,
- patient observations,
- assay data,
- manufacturing results,
- safety signals,
- and tacit experimental knowledge.
Historically, some of that knowledge disappeared when employees left.
Agents can potentially make more of it persistent.
The company becomes less dependent on individual recall.
Memory Could Matter More Than the Model
Frontier models will change.
A research organization may use one model this year and another next year.
The persistent asset is the organization's:
- context,
- data,
- permissions,
- experimental history,
- decision record,
- and provenance graph.
This mirrors what is happening in consumer agents.
The interface can change.
The model can change.
The accumulated context is what makes the system increasingly useful.
But Agentic Science Creates a New Problem: Provenance
Suppose 10,000 agents attempt a mathematics problem.
Agent 4,871 reads a public paper.
Agent 9,002 develops an idea related to it.
Agent 1,143 modifies that idea.
A consolidation agent merges several paths.
A proof agent formalizes the final result.
Who discovered it?
Which human work materially enabled the result?
Which dataset contributed?
Which licence applied?
Which previous researcher deserves citation?
Which organization owns the resulting IP?
Who is accountable if the result is wrong?
The Navier-Stokes dispute demonstrates that this is no longer an academic hypothetical.
DN Provenance Debt
DN calls unresolved attribution accumulated during machine-mediated research:
Provenance Debt.
Like technical debt, it can remain invisible while a system is moving quickly.
Then it becomes expensive.
A company may discover that:
- training materials have unclear rights,
- an agent relied on unpublished work,
- data licensing prevents commercialization,
- a patent claim overlaps prior art,
- contributors cannot be reconstructed,
- or regulators cannot audit how a scientific conclusion emerged.
As machine research becomes more parallel, provenance infrastructure becomes part of R&D infrastructure. The ability to prove where an idea, dataset, calculation and experimental conclusion came from may become economically inseparable from the discovery itself.
The Discovery Rights Stack
AI-mediated science can involve multiple overlapping rights.
| Layer | Question | Why it matters |
|---|---|---|
| Underlying publication | What prior research informed the agent? | Credit, copyright, reproducibility |
| Dataset rights | Who may access and reuse the data? | Commercialization and compliance |
| Existing patents | What claims already protect the asset? | Freedom to operate |
| Model contribution | What did the agent independently generate? | Authorship and inventorship questions |
| Human direction | What did researchers instruct, select or validate? | Responsibility and IP |
| Experimental proof | Who generated the validating evidence? | Scientific credibility |
| Regulatory evidence | Can outputs support a regulated decision? | Commercial translation |
| Commercial rights | Who may manufacture, license or sell? | Economic capture |
The Value Chain Is Moving Toward Validation
If AI makes first-pass intellectual work cheaper, several categories of infrastructure become more valuable.
1. High-quality scientific datasets
Agents cannot infer their way around missing ground truth forever.
2. Wet-lab capacity
More hypotheses require more physical testing.
3. Laboratory robotics
Self-driving laboratories can expand the rate at which machine hypotheses reach physical validation.
4. Clinical-trial networks
Human biology remains the ultimate constraint for therapeutics.
5. Scientific data standardization
Machine-readable experiments are easier to reuse.
6. Provenance infrastructure
Agent swarms require an auditable contribution graph.
7. IP marketplaces
Shelved programs become more useful if rights can be identified, priced and transferred efficiently.
8. Research prioritization
When hypotheses become abundant, selecting what deserves validation becomes increasingly valuable.
Self-Driving Labs Complete the Loop
The largest constraint on agentic science is that the physical world does not operate at token speed.
Chemicals must still react.
Cells must still grow.
Materials must still be synthesized.
Experiments take time.
But self-driving laboratories are narrowing that gap.
These systems combine:
- AI decision-making,
- robotics,
- automated experiment execution,
- measurement,
- and closed-loop analysis.
The machine can propose.
The robot can test.
The instrument can measure.
The model can update.
Then the cycle repeats.
Agentic science becomes economically transformative when digital hypothesis loops connect to physical validation loops. The critical metric is not how many ideas an AI can generate, but how quickly reality can reject them.
The Rejection Rate May Be More Valuable Than the Generation Rate
This sounds counterintuitive.
But if AI can generate one million candidate hypotheses, the world does not need another system producing ten million.
It needs a system that can eliminate 999,900 cheaply and reliably.
The future high-value scientific stack may therefore optimize for:
fast falsification.
That is a different business from generative AI.
It combines:
- experimental design,
- causal inference,
- robotics,
- data quality,
- and decision theory.
Scientific Search Could Become Capital Allocation
Once agentic science reaches enough scale, the problem starts to resemble portfolio management.
Every research hypothesis competes for scarce experimental capital.
The organization must allocate:
- lab time,
- scientists,
- samples,
- compute,
- regulatory effort,
- and money
among thousands of machine-generated possibilities.
Scientific management becomes a ranking problem.
Not a prediction leaderboard.
A capital-allocation engine.
The Best AI Lab May Behave Like a Quant Fund
A sophisticated future R&D organization could maintain thousands of scientific options simultaneously.
Each receives a dynamic score based on:
- evidence quality,
- novelty,
- replication,
- expected experiment cost,
- falsifiability,
- rights clarity,
- competitive activity,
- and potential impact.
Agents continuously update the portfolio.
Promising assets receive more experimental capital.
Weak hypotheses are killed quickly.
New external research can reactivate previously rejected programs.
The portfolio is never static.
Agentic R&D could transform scientific management from a sequence of projects into a continuously repriced portfolio of research options. The winners may be organizations best at allocating validation capital, not merely generating the most hypotheses.
The R&D Resurrection Rate
DN proposes another metric:
R&D Resurrection Rate.
It measures the share of previously shelved scientific assets that become credible candidates for new investigation after systematic agent review.
Importantly, this is not the percentage that eventually succeeds.
Those are very different things.
The resurrection threshold could simply mean:
the asset has enough new evidence to justify human diligence or another experiment.
Even a low resurrection rate can matter across a sufficiently large archive.
If only 1% of 5,523 shelved clinical programs warranted serious re-review, that would still produce more than 50 candidates.
That does not mean 50 drugs.
It means 50 options that were previously close to economically invisible.
The Economic Opportunity Extends Beyond Pharma
The same architecture could apply across many fields.
Materials science
Agents can revisit failed formulations as manufacturing methods and available materials change.
Battery research
Old chemistries can be reconsidered under new supply-chain economics or electrolyte technologies.
Semiconductors
Process ideas abandoned at one node can become relevant in chiplets, packaging or different materials systems.
Energy
Old geothermal surveys, nuclear engineering work, catalyst research and storage chemistries can be recombined with new economics.
Mathematics
Thousands of published lemmas and partial approaches can become searchable components of machine reasoning.
Industrial engineering
Retired designs can be re-evaluated when simulation, additive manufacturing or materials science changes feasibility.
Software
Old open-source projects can become machine-readable component libraries rather than abandoned repositories.
The Dormant IP Harvest Is Not a Free Lunch
The thesis has several serious constraints.
Garbage can become scalable garbage
Agents can process weak evidence faster too.
Correlation can create false consensus
Thousands of agents using similar models are not necessarily 10,000 independent scientists.
Existing data may contain hidden confounders
Biological data are particularly conditional and difficult to generalize.
Historical failure can still be real failure
AI cannot rescue a molecule that is fundamentally unsafe simply because it can summarize the file faster.
Rights may be unusable
An attractive scientific asset without clear ownership or freedom to operate may remain commercially stranded.
Experiment capacity does not scale like inference
A million digital hypotheses can still wait behind one physical laboratory door.
AI Drug Discovery Still Has to Prove Itself Clinically
This point deserves emphasis.
A major 2026 Nature Reviews Drug Discovery assessment concluded that evidence for clinically relevant AI impact in drug development remains limited.
The authors point to:
- data quality problems,
- conditional biology,
- underspecified real-world problems,
- translation failures,
- and too much emphasis on model performance rather than better decisions.
That criticism strengthens the Dormant IP Harvest thesis rather than weakening it.
It tells us where the value moves.
Away from generating more impressive model outputs.
Toward proving that machine-generated decisions improve real scientific outcomes.
DN Dormant IP Reactivation Monitor
Signals Worth Tracking
Track the public-market side of the agentic science buildout
Agentic research affects AI infrastructure, biotechnology, laboratory automation, semiconductor demand and scientific software. TradingView can be used to monitor the public companies and market signals around those themes. Affiliate link.
DN Dormant IP Reactivation Engine
The calculator below does not attempt to predict whether a drug, patent or research project will succeed.
It answers a more useful first-stage question:
How much of a dormant research portfolio is actually machine-ready, worth screening and capable of reaching physical validation?
Dormant IP Reactivation Engine
Model the searchability, rights quality, evidence strength and experimental bottlenecks inside a shelved R&D portfolio. All values are hypothetical user assumptions, not predictions of scientific success.
Calculating...
How to Read the Engine
The most important output is not the Reactivation Score.
It is the shape of the bottleneck.
A portfolio can contain excellent historical science while scoring poorly because the data cannot be reconstructed.
Another portfolio can be beautifully digitized but commercially unusable because ownership is unclear.
A third can produce hundreds of attractive hypotheses but have only enough laboratory capacity to test ten.
Those are different problems.
They require different investments.
Machine-Ready IP Ratio Could Become a Real Corporate Metric
Imagine a pharmaceutical company owns 4,000 archived research programs.
Management says this is a valuable library.
An investor should ask:
How many programs have:
- complete experimental records,
- structured underlying data,
- clear rights,
- known failure reasons,
- machine-readable methods,
- and current evidence attached?
If the answer is 200, then the company does not yet possess 4,000 machine-ready scientific options.
It possesses 200.
The other 3,800 require infrastructure work before agentic science can unlock them.
A New Kind of Digital Transformation
Companies spent the previous decade migrating enterprise workflows to the cloud.
The next migration could be:
from human-readable archives to machine-actionable institutional memory.
That means converting:
- PDFs into structured evidence,
- old experiments into searchable datasets,
- lab notebooks into provenance graphs,
- patent portfolios into machine-readable rights maps,
- failed programs into standardized post-mortems,
- and scientific software into callable tools.
The organization is not simply digitizing information.
It is turning history into working capital for agents.
The next enterprise-data boom may involve companies converting decades of accumulated knowledge into machine-actionable research memory. In that world, archives stop being storage costs and begin behaving like productive infrastructure.
Who Could Capture the Value?
The obvious beneficiaries are not necessarily the companies with the flashiest general-purpose model.
Pharmaceutical companies with deep archives
Decades of proprietary negative and positive data could become more valuable when systematic machine re-analysis becomes cheap.
Biotech asset marketplaces
AI could reduce the search cost between owners of shelved programs and buyers willing to restart them.
Scientific publishers
Machine-executable papers could create new products around methods, data access and research agents.
Laboratory automation providers
Hypothesis inflation increases demand for physical validation throughput.
Cloud and compute providers
Large-scale research swarms convert scientific problems directly into inference demand.
Scientific-data infrastructure
Clean, standardized and permissioned datasets become increasingly valuable.
Research provenance platforms
Organizations need to trace contributions through millions of agent interactions.
Clinical networks
Digital intelligence cannot substitute for human biological evidence where clinical validation is required.
The Biggest Mispricing May Be in Research Infrastructure
Markets naturally focus on spectacular AI outputs.
A theorem.
A molecule.
A new material.
A scientific discovery.
But if those outputs become more frequent, the scarce layer moves underneath them.
The market may eventually discover that the valuable businesses are the ones controlling:
- the clean data,
- the laboratories,
- the robotics,
- the samples,
- the rights,
- the provenance,
- and the experimental throughput.
The Scarcity Inversion
DN calls this:
The Scientific Scarcity Inversion.
Before powerful agentic AI:
high-quality intellectual labour was scarce.
After sufficiently capable agentic AI:
machine-generated intellectual labour can become abundant.
The scarce layers then migrate toward things that cannot be copied with another token.
Physical reality.
Exclusive data.
Rights.
Trust.
Samples.
Lab capacity.
Human participants.
And time.
What Would Prove This Thesis Wrong?
The Dormant IP Harvest thesis weakens materially if:
- agent systems continue to perform poorly on realistic scientific workflows,
- multi-agent scaling produces mostly correlated errors rather than better research,
- most shelved scientific assets prove to have been abandoned for fundamental scientific reasons,
- historical datasets are too fragmented or low-quality to produce useful machine analysis,
- IP and data rights make systematic reuse commercially impractical,
- scientific institutions refuse to make methods and evidence machine-accessible,
- experimental validation capacity scales quickly enough that no meaningful bottleneck appears,
- or AI-generated hypotheses fail to improve real-world research decisions despite impressive benchmark performance.
The strongest falsification would be simple.
If agentic science generates far more papers, hypotheses and computational discoveries but does not improve the rate of validated scientific progress, then much of the apparent productivity gain is informational noise.
The Bigger Conclusion
Human civilization does not suffer from a shortage of recorded knowledge.
It suffers from an inability to continuously interrogate all of it.
A scientist cannot read every paper.
A pharmaceutical executive cannot personally revisit every abandoned molecule.
A mathematician cannot inspect every relevant lemma.
An engineer cannot rerun every discarded design.
A company cannot keep every departing employee's tacit research knowledge alive.
Agents change the economics of that limitation.
They can read in parallel.
Search in parallel.
Compare in parallel.
Code in parallel.
Simulate in parallel.
Critique in parallel.
And increasingly coordinate those activities.
That does not mean science becomes automatic.
It means the frontier of scarcity moves.
From finding an idea
to proving it.
From remembering a paper
to validating its consequence.
From generating a hypothesis
to deciding which hypothesis deserves scarce experimental capital.
From storing knowledge
to proving where that knowledge came from.
The next AI gold rush may therefore occur somewhere less obvious than the frontier-model leaderboard.
It may happen inside humanity's research archive.
Not because everything we abandoned was secretly correct.
Most of it probably was not.
But because for the first time, it may become economically possible to ask every forgotten experiment the same question:
Are you still dead?
Primary Sources & Evidence
- Nature, Reimagining Research Papers as Interactive and Reliable AI Agents, September 16, 2026.
- Stanford Medicine, AI Agents Built From Scientific Papers Surface New Discoveries, September 16, 2026.
- Science, The Virtual Biotech: A Multi-Agent AI Framework for Therapeutic Discovery and Development, September 17, 2026.
- Nature, How a Team of AIs Discovered a Promising Lung-Cancer Drug, September 17, 2026.
- Nature, A Multi-Agent System for Automating Scientific Discovery, May 19, 2026.
- Nature, Accelerating Scientific Discovery With Co-Scientist, 2026.
- Stanford HAI, 2026 AI Index Report, Science.
- Drug Discovery Today, Estimating the Global Inventory of Deprioritized Clinical-Stage Drug Development Programs: Toward a Market for Shelved Assets, 2026.
- US Food and Drug Administration, Drug Repurposing for Unmet Medical Needs, 2026.
- Nature Reviews Drug Discovery, Artificial Intelligence in Drug Discovery: What It Is, Where We Stand and the Path Forward, August 2026.
- Nature Reviews Chemistry, The Past, Present and Future of Self-Driving Laboratories, July 2026.
- OpenAI, On the Navier-Stokes Millennium Prize Problem, September 8, 2026.
- Nature, AI Companies Must Work With the Research Community to Protect Attribution, September 16, 2026.
- World Intellectual Property Organization, Patent Trends Update in Generative AI, 2026.
Frequently Asked Questions
What is the Dormant IP Harvest?
The Dormant IP Harvest is a Decentralised News framework describing the potential for AI agents to systematically search and re-evaluate abandoned research, shelved development programs, patents, datasets and negative experimental results that may retain scientific option value.
Does this mean failed drugs can simply be revived with AI?
No. Many drugs fail because they are unsafe or ineffective, and AI does not remove those biological constraints. The opportunity is to reduce the cost of identifying the smaller subset of discontinued programs that deserve another look because new evidence, technology or development strategies may have changed the original economics or scientific thesis.
What is Scientific Option Value?
Scientific Option Value is DN terminology for the residual potential of a shelved research asset when prior evidence, new scientific developments, rights clarity and affordable validation create a credible reason to reconsider it.
What is the Coordination Tax?
The Coordination Tax is the time and economic cost required to find, understand, reproduce and combine fragmented scientific knowledge across researchers, papers, datasets, software and organizations.
What is Hypothesis Inflation?
Hypothesis Inflation describes a scenario in which AI systems generate credible testable ideas much faster than laboratories or clinical systems can validate them, shifting scarcity from idea generation toward physical experimentation.
What is Validation Capital?
Validation Capital refers to scarce resources required to prove or falsify machine-generated scientific hypotheses, including wet labs, equipment, samples, robotics, expert review, clinical participants, regulatory infrastructure and high-quality data.
What is the Machine-Readable IP Discount?
The Machine-Readable IP Discount is DN's term for the potential reduction in useful value of historical research that is difficult for AI systems to access because documentation, metadata, source data, ownership records or experimental provenance are incomplete.
What is Provenance Debt?
Provenance Debt is unresolved uncertainty about where machine-mediated research conclusions originated, including contributing publications, datasets, model outputs, prior researchers, licences and experimental evidence.
Are AI agents already better than scientists?
Performance is highly uneven. AI systems have produced impressive scientific demonstrations, but 2026 benchmarks still show major gaps on realistic end-to-end research tasks. Human expertise, experimental validation and oversight remain critical.
Why could negative experimental results become more valuable?
Negative results can prevent agents from repeatedly exploring paths that have already failed. As machines search larger scientific possibility spaces, high-quality failure data can help prune that search and improve capital allocation.